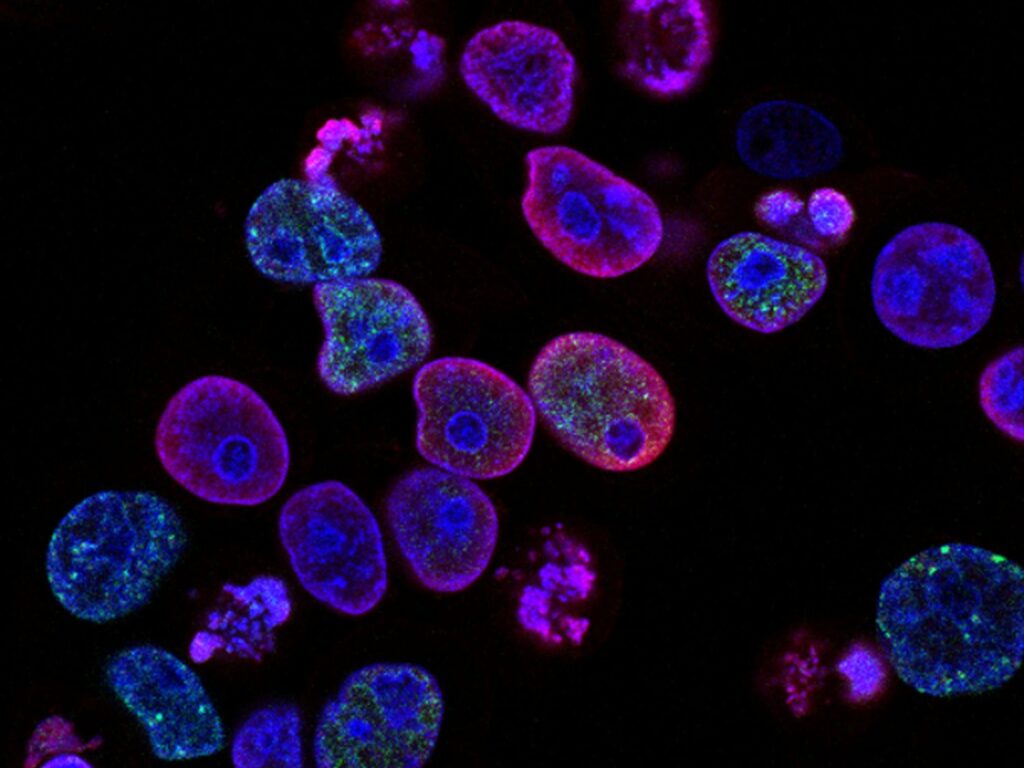
Built by Paige and Microsoft, PRISM2 reads whole-slide images through a perceiver-based encoder trained jointly on tissue tiles and clinical dialogue drawn from pathology reports. The model aggregates thousands of tile embeddings per slide into one representation, then generates text that answers diagnostic questions rather than simply classifying pixels.
Training data spans 2.3 million whole-slide images. The dialogue supervision comes from 685,507 pathology reports that Memorial Sloan Kettering Cancer Center collected during routine care, converted into question-and-answer pairs by GPT-4o.
Architecture and embedding design
The architecture…
Read the full article at ARTIFICIALINTELLIGENCE-NEWS.COM