
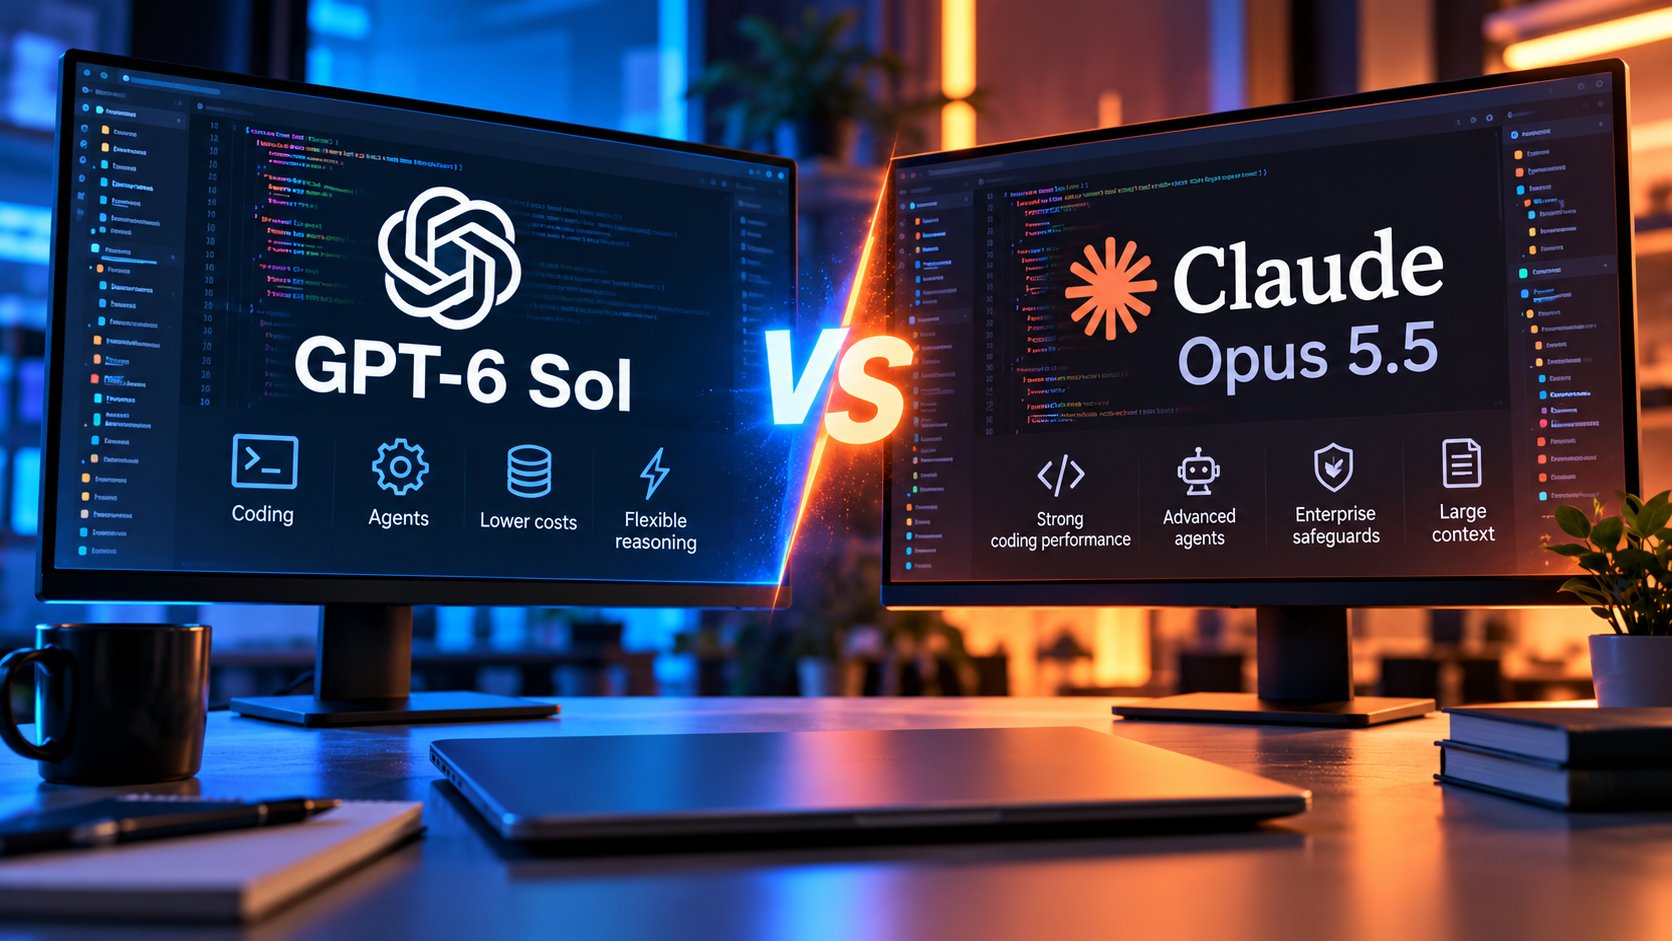
OpenAI and Anthropic released GPT-6 Sol and Claude Opus 5.5 on Sept. 22, 2026, putting two new coding- and agent-focused models in direct competition.
GPT-6 Sol starts at half the standard API price of Opus 5.5, while Claude posts stronger results in several current coding benchmarks. The gap changes once prompts get very large, and the two models also differ in reasoning controls, deployment options, and safeguards.
For teams choosing between them, the better fit depends on how much context a workload uses, how much reasoning it needs, and whether coding, automation, or enterprise controls matter most.
GPT-6 Sol vs Claude Opus 5.5 at a glance
| GPT-6 Sol | Claude Opus 5.5 | |
|---|---|---|
| Standard input | $2 per 1M tokens | $4 per 1M tokens |
| Standard output | $10 per 1M tokens | $20 per 1M tokens |
| Cache read | $0.20 per 1M tokens | $0.20 per 1M tokens |
| Long-context pricing | Higher rates above 272K input tokens | Standard rates through 1M context |
| Context window | 1.05M tokens | 1M tokens |
| Max standard output | 128K tokens | 128K tokens |
| Reasoning controls | None, low, medium, high, xhigh, max | Low, medium, high, xhigh, max |
| Thinking off | ✔ | ✖ |
| Coding environment | Codex | Claude Code |
| API model ID | gpt-6-sol |
claude-opus-5-5 |
How we compared GPT-6 Sol and Claude Opus 5.5
We compared the two models across the areas most likely to affect real coding and agent deployments:
- Pricing: Input, output, caching, and long-context costs.
- Coding: Repository work, terminal tasks, debugging, refactoring, and software-engineering benchmarks.
- Agents: Tool use, automation, long-running tasks, and multi-step execution.
- Reasoning: Available effort settings and whether extended reasoning can be disabled.
- Context: Maximum context and output limits for large codebases and documents.
- Deployment: API availability, coding environments, cloud platforms, and enterprise controls.
- Safeguards: Restrictions or verification requirements that can affect higher-risk workloads.
OpenAI positions Sol as a lower-cost model for coding and agentic work beneath its more expensive GPT-6 Astra model. Anthropic describes Opus 5.5 as its model for long-running agentic coding and knowledge work.
GPT-6 Sol is cheaper until context gets very large
OpenAI prices GPT-6 Sol at $2 per million input tokens and $10 per million output tokens. Cached input costs $0.20 per million tokens, while cache writes cost $2.50.
Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens. Cache reads also cost $0.20 per million tokens, while a five-minute cache write costs $5.
That gives Sol a clear advantage for standard workloads: half the uncached input and output price, with the same cache-read rate.
The math changes once a Sol request exceeds 272,000 input tokens. OpenAI then charges the entire request at $4 per million input tokens, $0.40 for cached input, $5 for cache writes, and $15 per million output tokens.
At that point, Sol’s input and cache-write prices match Opus 5.5, cached reads cost twice as much, and output remains 25% cheaper.
Anthropic does not add a separate long-context price tier within Opus 5.5’s 1 million-token window.
For smaller and medium-size coding or automation jobs, Sol keeps the larger price advantage. Teams repeatedly loading large repositories, long histories, or heavy retrieval context need to model that 272K threshold separately.
Sol gives developers more control over reasoning
GPT-6 Sol supports a 1.05 million-token context window and up to 128,000 output tokens.
Claude Opus 5.5 supports a 1 million-token context window with the same 128,000-token standard output limit. Anthropic also offers up to 300,000 output tokens through its Message Batches API in beta.
The bigger difference is how reasoning works.
Sol supports none, low, medium, high, xhigh, and max. Selecting none turns extended reasoning off completely.
That can be useful when a workflow mixes simple, repetitive calls with harder jobs that benefit from more reasoning. Teams can spend more compute only when they need it.
Opus 5.5 uses adaptive thinking that is always on. Developers can choose low, medium, high, xhigh, or max, with medium as the default, but they cannot fully disable thinking.
Neither approach is automatically better. Sol offers more control over latency and reasoning use, while Claude keeps adaptive reasoning active across every request.
Claude leads several current coding benchmarks
Independent testing currently gives Claude Opus 5.5 an advantage on several coding and agent benchmarks, although the size of the lead changes with effort settings.
At high effort, Artificial Analysis measured Opus 5.5 at 57% on Terminal-Bench 4.0 versus 26% for Sol.
The models were much closer on AutomationBench-AA, where Claude scored 63% and Sol 60%, and on SciCode, where the results were 60% and 55%.
Sol closes part of the gap at max effort. Artificial Analysis measured it at 62% on AutomationBench-AA against Claude’s 63% at high effort, while SciCode narrowed to 58% versus 60%. Terminal-Bench remained farther apart at 44% for Sol and 57% for Claude.
That makes workload type important. Claude currently has the clearer edge on terminal-heavy coding tasks, while agent automation is much closer.
Benchmark scores also do not tell teams how much usable work reaches production. A Microsoft study of AI coding agents found that regular use was associated with 24% more merged pull requests, but adoption, repository age, and review capacity all affected the result.
For production decisions, teams should run both models against their own repositories rather than assume one leaderboard reflects every coding environment.
Agent costs depend on more than token prices
Agent workflows can use far more than a single prompt and response.
A coding agent may inspect files, call tools, run tests, revise its plan, retry failed steps, and generate additional output before completing one task. That means a model with a higher token price can still be economical if it finishes the work in fewer steps.
The opposite is also true. Sol’s lower standard rates can add up to meaningful savings in high-volume workflows where tasks are predictable and do not need maximum reasoning.
OpenAI built Sol specifically for coding and agentic workflows, while Anthropic says Opus 5.5 costs about 40% less to run than Opus 5 on typical token-billed workloads.
The surrounding products also matter. Sol is available through the OpenAI API, Codex, and ChatGPT Work, while Opus 5.5 is available through Claude, Claude Code, the Claude API, Amazon Bedrock, Google Cloud, and Microsoft Foundry.
Those environments provide different tools, permissions, integrations, and workflows. Our ChatGPT Work vs Claude comparison looks at those broader agent platforms rather than the underlying models alone.
Safety controls differ for higher-risk work
Anthropic applies additional controls to Opus 5.5 for some cybersecurity, biology, and model-distillation work.
Routine software-development tasks such as identifying and fixing bugs can run on Opus 5.5. Anthropic says most other cybersecurity requests are routed to Opus 4.8 unless the user qualifies for more permissive verified access.
Anthropic has opened a Life Sciences Verification Program and says it plans to expand its Cyber Verification Program to Opus 5.5. The model is also available with zero data retention.
OpenAI’s public Sol documentation focuses on pricing, reasoning, tools, API behavior, and data residency rather than describing an equivalent Sol-specific cybersecurity routing system.
That does not remove the need for controls around either model. OpenAI’s recent findings on agent behavior reinforced the importance of data-access boundaries, including scoped credentials, approval rules, and audit logs when agents can reach external systems.
Teams working in regulated or security-sensitive environments should test those restrictions before deployment instead of assuming the same task will run identically on both platforms.
Which model should you choose?
GPT-6 Sol is the stronger fit when API cost is a priority, and most workloads stay below 272,000 input tokens. Its standard input and output rates are half of Opus 5.5’s, and developers can switch extended reasoning off entirely for simpler jobs.
Claude Opus 5.5 currently performs better on several independent coding benchmarks, particularly Terminal-Bench. It also keeps the same pricing across its 1 million-token context window, which can make the cost difference much smaller for consistently large prompts.
For agent automation, the decision is less clear. The two models test much closer on AutomationBench-AA, especially when Sol runs at higher effort.
Teams should run the same representative tasks through both models before standardizing. Use identical prompts, tools, repositories, and acceptance criteria, then track completed tasks, human correction time, latency, retries, token use, and total cost.
That gives a much better buying signal than either headline API pricing or a single benchmark score.
Want to learn more AI tips, tricks, and prompting techniques? TechRepublic readers get free 7-day access to The Neuron Academy, our practical learning platform designed to help professionals use AI more confidently at work. Browse all lessons →
Let us teach you How to Talk to AI for free! Try our six-minute course at The Neuron Academy and learn a few simple ways to write better prompts and get more useful results from AI, or browse our other AI course for free for seven days. Check out all the lessons here →
Read the full article here